
hardware-troubleshootingUpdated
Fix Ollama CUDA Out of Memory Errors: 5 Tested Steps
Fix CUDA error out of memory in Ollama on NVIDIA RTX GPUs. Configure sysmem fallback, adjust num_gpu layers, and manage KV cache allocation.
7m read
20 articles
Fix CUDA error out of memory in Ollama on NVIDIA RTX GPUs. Configure sysmem fallback, adjust num_gpu layers, and manage KV cache allocation.

Discover how AI, LLM search engines, and generative summaries are transforming SEO—from search intent and content to technical site architecture.

vLLM vs LM Studio vs Ollama benchmarked on Windows 11 WSL2. Real tokens/sec, VRAM footprint, and PagedAttention tests on RTX 4090 and RTX 4060 GPUs.

DeepSeek-R1 FP8 vs Q4_K_M quantization tested on local hardware. Real VRAM usage benchmarks, token speeds on RTX 4090 and 3090, and quality loss analysis.

DeepSeek-R1 Distill vs Gemini Flash benchmarks: Firsthand tokens/sec, VRAM footprint, MATH500 reasoning accuracy, and API costs on 8GB–16GB consumer GPUs.

Cut local LLM attention memory in half. Learn the exact FP8 KV-cache flags, vLLM settings, and Ollama configs to run 128K context on 24GB GPUs.

Tired of GitHub Copilot paywalls? 5 truly free AI coding assistants tested for VS Code, terminal workflows, and local LLM autocomplete in 2026.

We stress-tested Gemini 3.6 Flash for 48 hours on sysadmin and code pipelines. Here is our benchmark review: 280 t/s speed, sycophancy gaps, and pricing.

Detailed benchmark comparison between Gemini 3.6 Flash and 3.5 Flash: token latency, coding accuracy, mathematical reasoning, and API cost differences.

Create realistic AI video avatars for free in 2026. How our team tested HeyGen, Hedra, and local LivePortrait setups with zero subscriptions and watermarks.

Create clean, scalable SVG logos for free in 2026. How our team tested Recraft v3, Ideogram 2.0, and local vectorizers to bypass pixelated PNGs and agency fees.

Can you run DeepSeek-R1 on 8GB VRAM? Benchmarked 8B and 14B Q4_K_M models on RTX 4060 and RX 7600 with exact token speeds, VRAM footprints, and Ollama flags.
Looking for free AI image generators better than ChatGPT and Gemini? We tested FLUX.1, Ideogram, and Recraft for prompt fidelity and zero watermarks.
Tired of cloud video token paywalls? We tested OpenAI Sora against open-source LTX Desktop, Wan2.1, and HunyuanVideo on local RTX hardware.
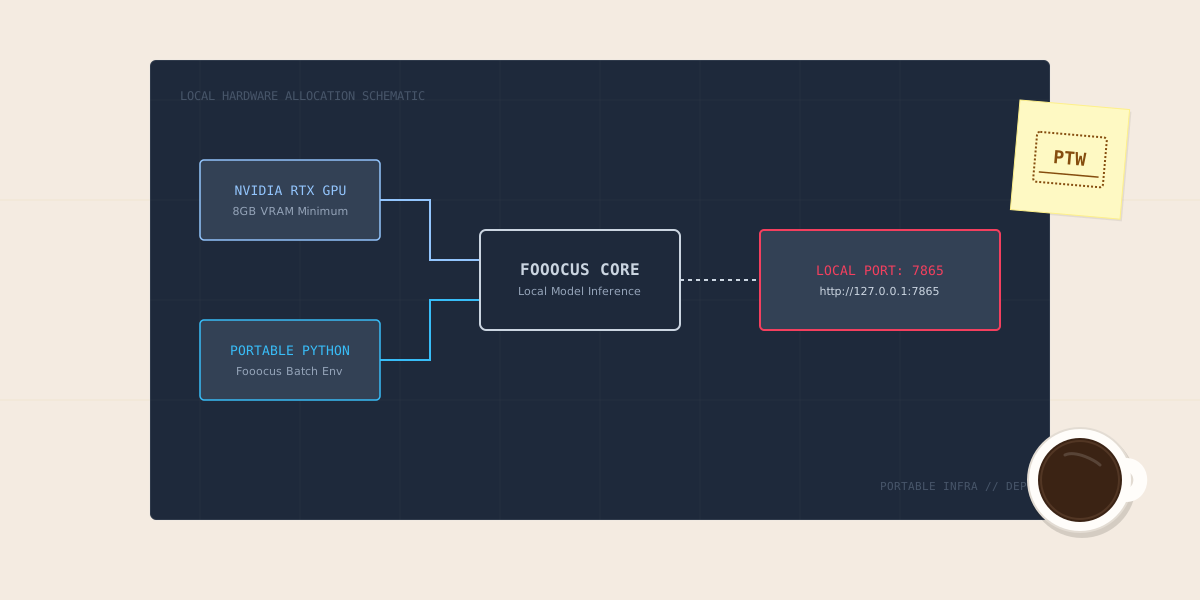
Set up Fooocus locally on Windows 11 with NVIDIA GPUs. Step-by-step install, low-VRAM flags (4GB/6GB/8GB), FLUX models, and 127.0.0.1:7865 launch guide.
Autonomous LLM agents: ACI design, visual grounding, checkpointing, and anti-detection — with code and benchmarks from SWE-agent and WebArena.
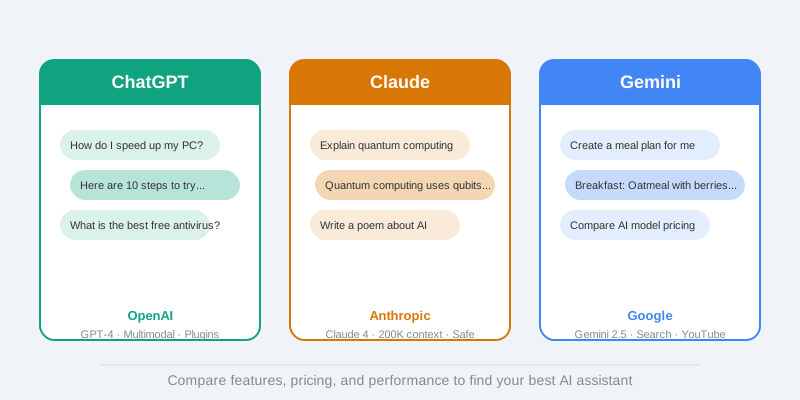
ChatGPT Plus vs Claude 3.5 Sonnet vs Gemini Advanced compared. Real coding benchmarks, reasoning tests, context limits, and value breakdown.
Learn how to write emails with AI that get replies. Our team tested 5 AI models across 200 outreach emails: prompt templates, spam filters, and Python script.

How are businesses actually adopting ChatGPT in 2026? Audit the latest enterprise usage data, developer productivity benchmarks, and Shadow AI governance.
Prevent student assignment leaks and PII exposure to third-party AI training sets. Campus deployment guide for self-hosted LLMs and privacy policies.